
AI Benchmarks & Leaderboard — 2026-10-17
Meta has released "Muse Spark Open," a new open-weight model aimed at complex software engineering and multi-step reasoning, while DeepSeek quietly pushed its "V4.1-Flash-1017" update directly to its live API, scoring 77.0 on the DeepSWE benchmark. These releases highlight a continuing trend of aggressive updates from Chinese labs and Meta, with Artificial Analysis confirming Claude Opus 5.5 and Muse Wonder Full as current leaders in intelligence.
AI Benchmarks & Leaderboard — 2026-10-17
New Model Releases & Updates
Muse Spark Open by Meta
- Type: Open-weight AI model
- Key benchmarks: Not explicitly detailed in the initial release, but positioned for "multi-step reasoning" and "complex software engineering."
- vs. Previous best: Represents Meta's continued push to catch up with Chinese rivals in the open-weight space.
- What's notable: Meta claims the model excels in reasoning and software engineering tasks, aiming to provide a strong open alternative to closed frontier models.

DeepSeek-V4.1-Flash-1017 by DeepSeek
- Type: API model update (Flash variant)
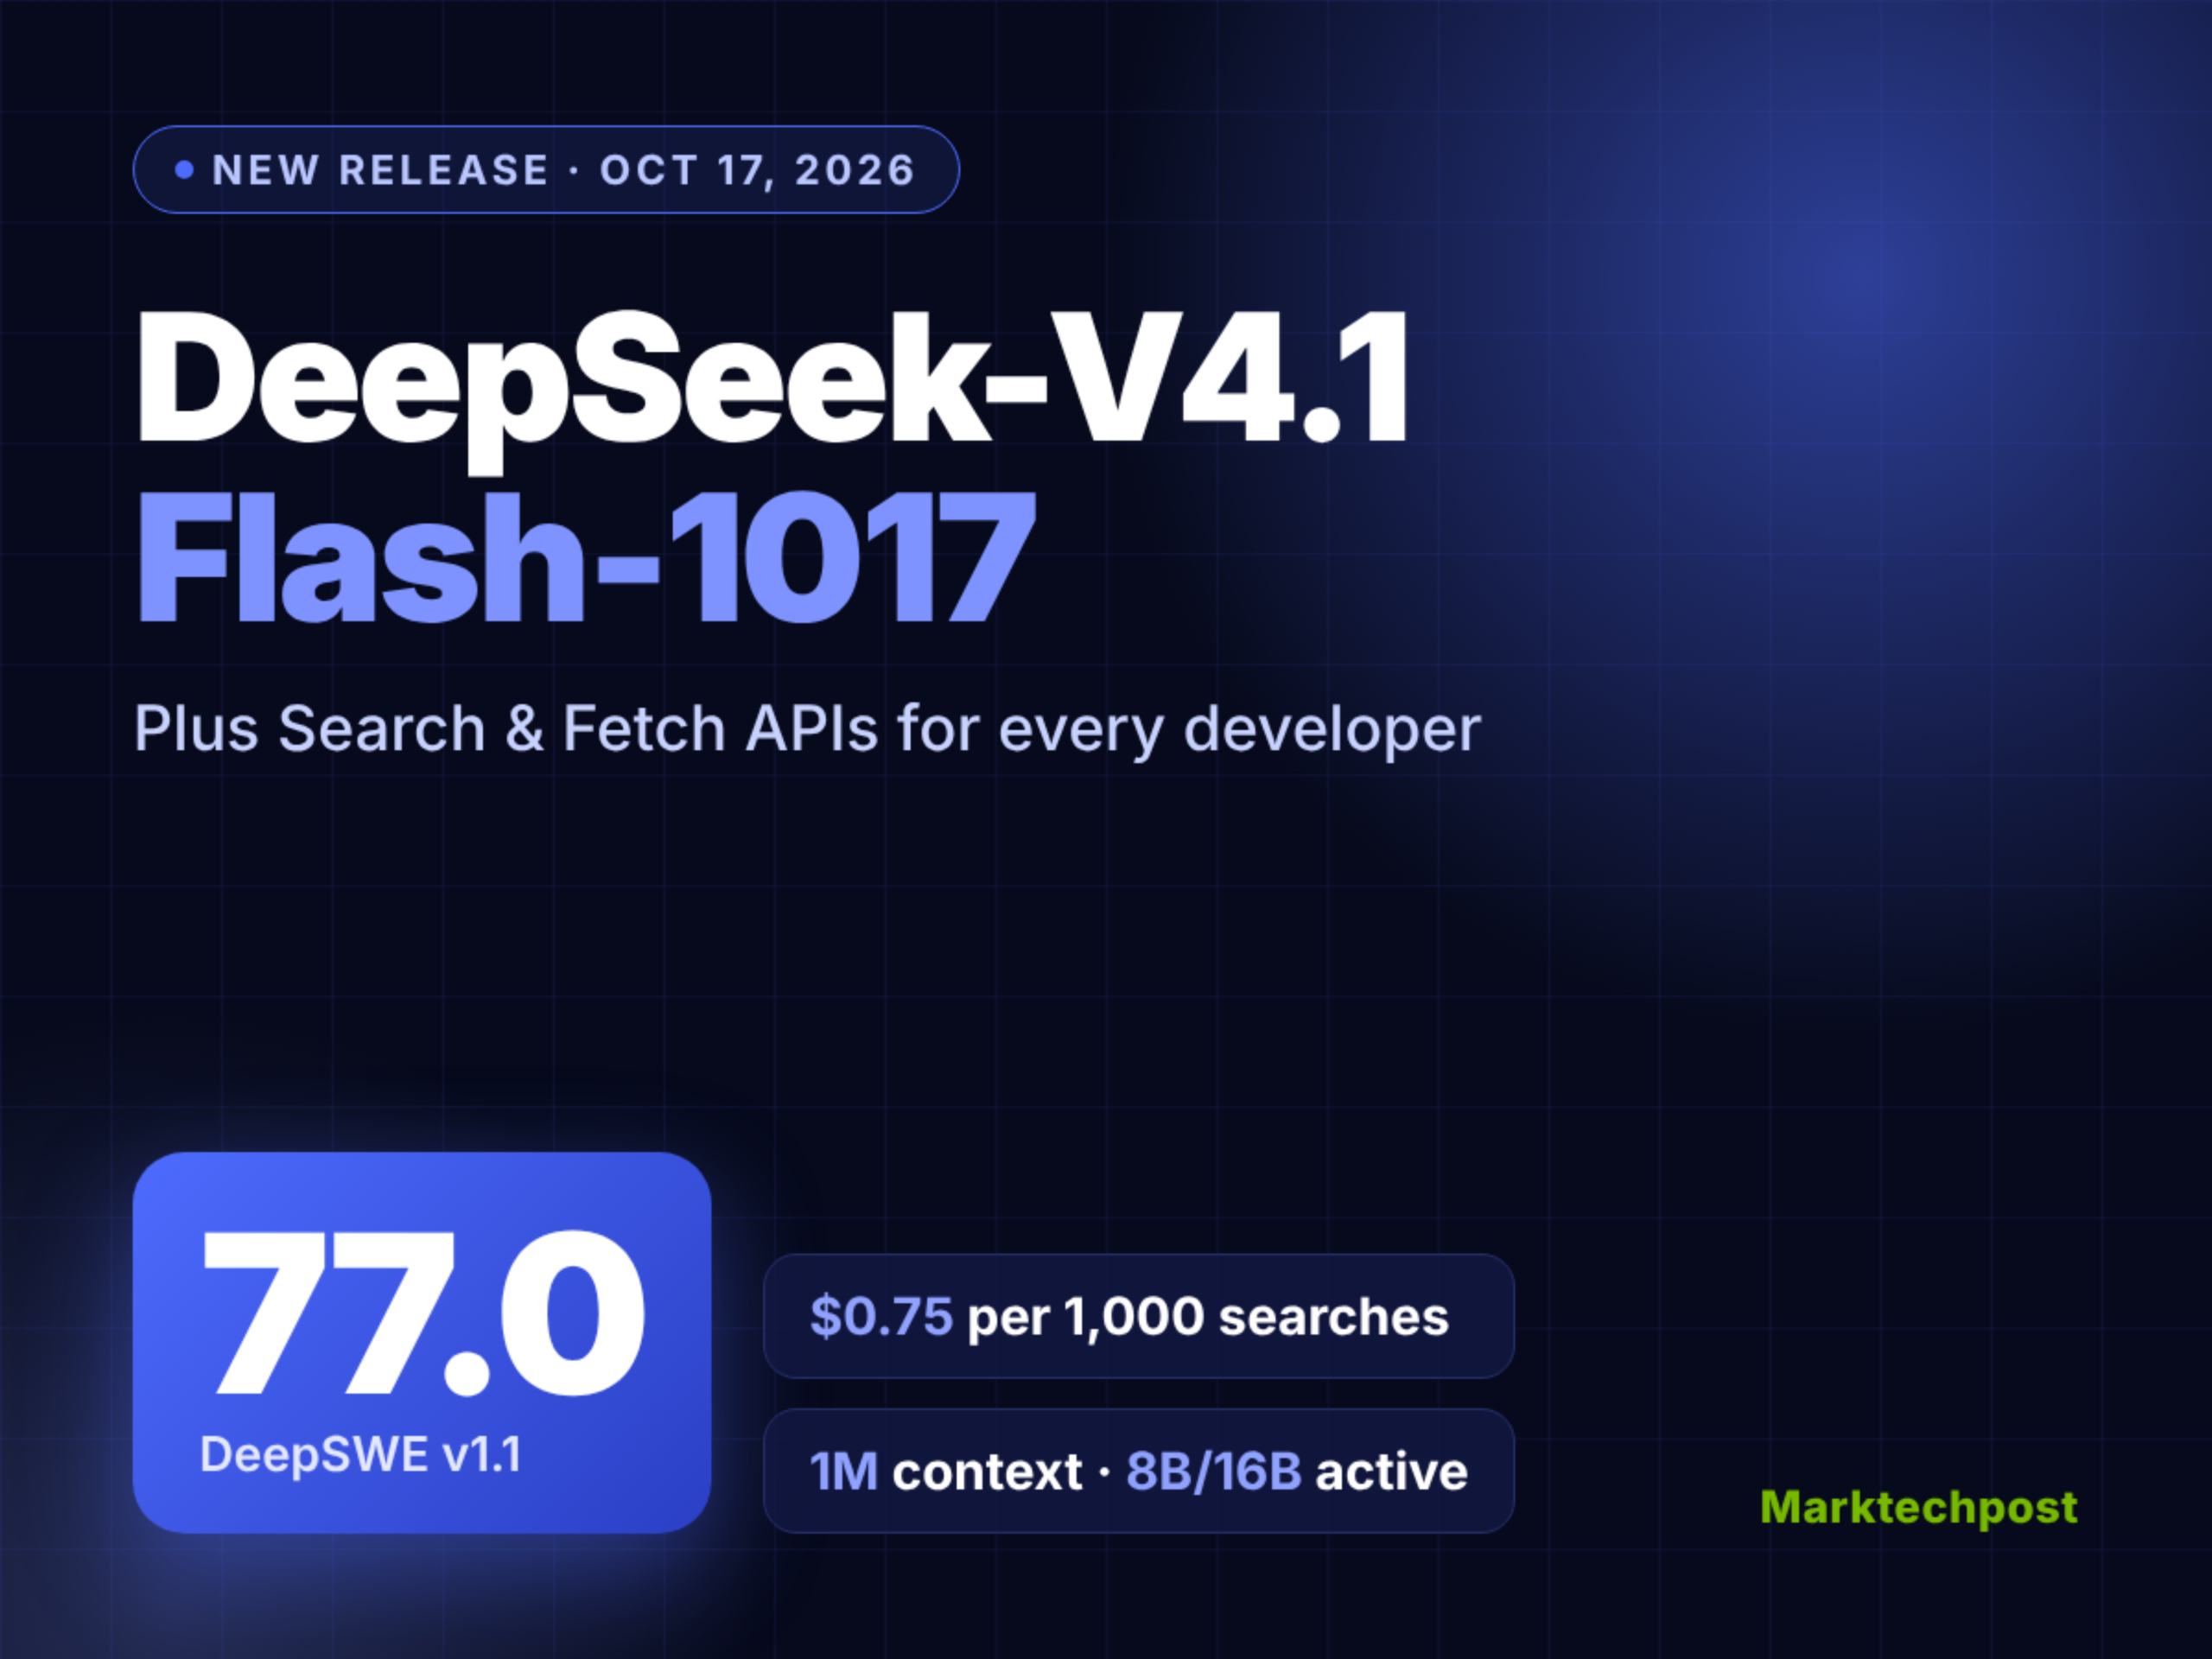
- Key benchmarks: Scores 77.0 on DeepSWE v1.1.
- vs. Previous best: A quiet update pushed directly to the live API, briefly leaked before being confirmed on Vercel's AI Gateway and Hugging Face.
- What's notable: DeepSeek also opened its Search and Fetch APIs at $0.75 per 1,000 calls alongside this model release.
Liquid AI LFM2.5-24B-A2B by Liquid AI
- Type: Open-weight model (24B parameters, A2B architecture)
- Key benchmarks: Beats Qwen3.6 on tool use, but trails on SWE-Bench.
- vs. Previous best: Positioned within the October 2026 open-model wave as a specialized alternative.
- What's notable: Highlights the ongoing competition in specialized capabilities like tool use versus general software engineering benchmarks.
Leaderboard Snapshot
Frontier Models (Closed-Source)
| Model | Provider | Notable Strengths | Key Score |
|---|---|---|---|
| Claude Opus 5.5 (max with fallback) | Anthropic | Highest overall intelligence | Artificial Analysis Intelligence Index Leader |
| Claude Sonnet 5.5 (max with fallback) | Anthropic | High intelligence, balanced performance | Artificial Analysis Intelligence Index Leader |
| Muse Wonder Full (max) | Meta | Strong reasoning, complex software engineering | Artificial Analysis Intelligence Index Leader |
| Gemini 3.8 Flash | Reaches Intelligence vs. Cost per Task Pareto frontier | 59 on Artificial Analysis Intelligence Index | |
| Anthropic's New Frontier Model | Anthropic | Leads on agentic knowledge work | 66 at max effort |
Open-Source Leaders
| Model | Parameters | Notable Strengths | Key Score |
|---|---|---|---|
| DeepSeek-V4.1-Flash-1017 | N/A (API) | Software engineering, Search/Fetch API integration | 77.0 on DeepSWE v1.1 |
| Liquid AI LFM2.5-24B-A2B | 24B | Tool use | Beats Qwen3.6 on tool use |
| Qwen3.6 | N/A | General open-source baseline | Trails LFM2.5 on tool use |
| Muse Spark Open | N/A | Multi-step reasoning, complex software engineering | N/A |
| K2 Horizon 375B A23B | 375B | Lowest cost per task | Artificial Analysis Cost Leader |
Benchmark Deep Dive: DeepSeek's Quiet API Update
A significant development this week was DeepSeek's quiet push of the V4.1-Flash-1017 update directly into its live API. This model scored 77.0 on the DeepSWE v1.1 benchmark, a specialized evaluation for software engineering capabilities. The update was initially leaked in the API before trackers confirmed its official release on platforms like Vercel's AI Gateway and Hugging Face.
Alongside the model update, DeepSeek also opened its Search and Fetch APIs, pricing them at $0.75 per 1,000 calls. This move signals a broader trend of API providers bundling specialized tools (like search and fetch) with their core LLM offerings, potentially shifting how developers integrate external knowledge retrieval into their applications. The DeepSWE score of 77.0 positions this Flash variant as a strong contender for coding and software engineering tasks, though the quiet nature of the release suggests a more iterative development cycle compared to major version launches.
Analysis & Trends
- State of the art: Claude Opus 5.5 and Sonnet 5.5 remain the highest intelligence models according to Artificial Analysis, followed closely by Meta's Muse Wonder Full. Anthropic's new frontier model leads specifically in agentic knowledge work.
- Open vs. Closed gap: Chinese labs continue to take the open-weight crown, with models like DeepSeek V4.1-Flash and Qwen 3.8 showing strong performance. Meta's Muse Spark Open is explicitly aimed at catching up to these Chinese rivals in the open-weight space.
- Cost-performance: K2 Horizon 375B A23B and Gemma 4 31B currently offer the lowest cost per task. Gemini 3.8 Flash is noted for reaching the Intelligence vs. Cost per Task Pareto frontier.
- Emerging patterns: There is a clear trend of models specializing in specific tasks, such as tool use (Liquid AI LFM2.5) and software engineering (DeepSeek V4.1-Flash), rather than just general reasoning.
What to Watch Next
- Chinese Open-Weight Dominance: Chinese open AI models are increasingly offering top performance at lower costs, outperforming Western rivals despite chip sanctions and tighter compute limits.
- API Tooling Integration: DeepSeek's launch of Search and Fetch APIs alongside V4.1-Flash suggests other providers may follow suit, bundling retrieval tools with model access.
- Meta's Open-Weight Strategy: Meta's release of Muse Spark Open indicates a strategic push to reclaim ground in the open-weight model space, specifically targeting reasoning and coding tasks.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
