
AI Benchmarks & Leaderboard — 2026-10-13
Meta released Muse Wonder and Muse Wonder Full, introducing a new tiered pricing model and benchmarking against Claude Opus 5.5. The latest Artificial Analysis Intelligence Index continues to be led by Anthropic's Claude Opus 5.5, while the industry sees a surge in specialized decision models beyond traditional LLMs.
AI Benchmarks & Leaderboard — 2026-10-13
New Model Releases & Updates
Muse Wonder & Muse Wonder Full by Meta
- Type: Closed-source (API access via Meta Model API)
- Key benchmarks: Benchmarking against Claude Opus 5.5 for agentic coding and general reasoning tasks.
- vs. Previous best: Positioned as a direct competitor to top-tier frontier models like Claude Opus 5.5, with "Full" running exclusively inside Muse Code on premium plans.
- What's notable: Released October 12, 2026. The release introduces a split-access model: standard "Wonder" is available via API at $4/$20 per million tokens, while "Full" is gated to Muse Code users on $50/$200 subscription plans.
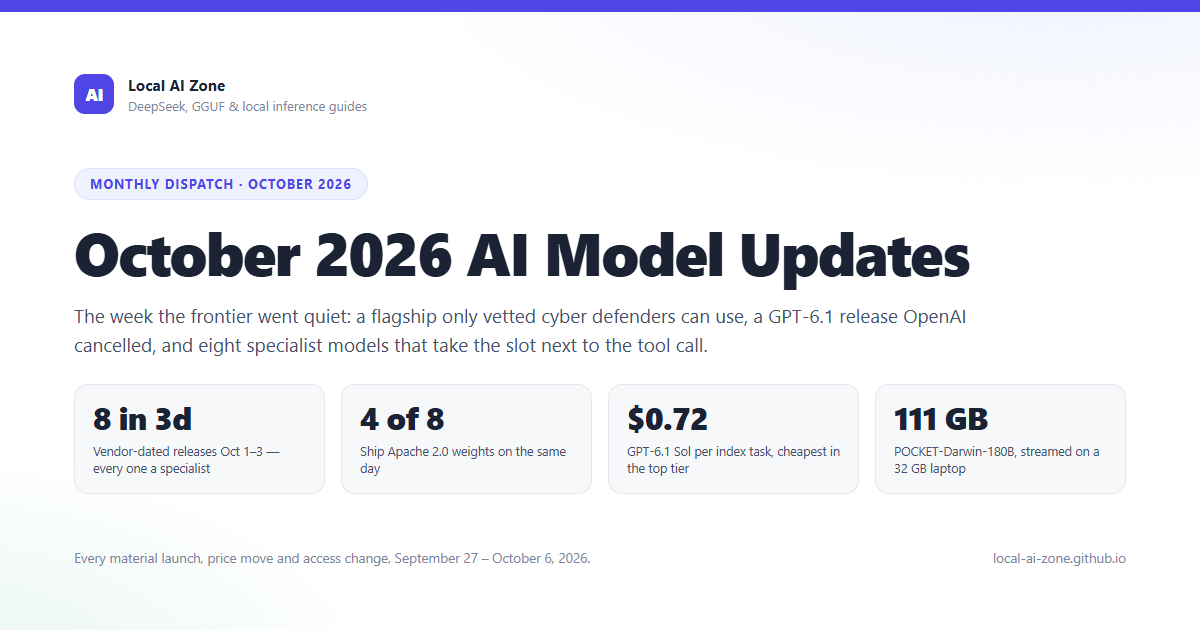
AI Decision Models (New Wave)
- Type: Specialized decision AI (Commercial APIs and locally hosted open-source).
- Key benchmarks: Not specified in general overview, but focused on specialized decision tasks rather than general language generation.
- vs. Previous best: Offers alternatives to traditional Large Language Models (LLMs) for specific decision-making workflows.
- What's notable: A growing market of specialized "decision AI" is emerging as developers seek alternatives to general-purpose LLMs for specific operational tasks.
Leaderboard Snapshot
Frontier Models (Closed-Source)
| Model | Provider | Notable Strengths | Key Score |
|---|---|---|---|
| Claude Opus 5.5 (max w/ fallback) | Anthropic | Highest Intelligence Index | 58 |
| Claude Sonnet 5.5 (max w/ fallback) | Anthropic | High output tokens per task | 56 |
| GPT-6 Astra | OpenAI | High intelligence, lower cost | 57 |
| Muse Wonder Full (max) | Meta | High intelligence, coding focus | N/A |
| Gemini 4 Argon | Access restricted to Fairwind defenders | N/A |
Open-Source Leaders
| Model | Parameters | Notable Strengths | Key Score |
|---|---|---|---|
| Llama 4 Scout | Unknown | Largest context window | N/A |
| Celeris-1 | Unknown | Fastest speed (1,532 t/s) | N/A |
| Granite 4.2 3B | 3B | Most affordable ($0.02/1M tokens) | N/A |
| Mercury 2.5 | Unknown | Second fastest speed (711.8 t/s) | N/A |
| K2 Horizon 375B A23B | 375B | Lowest cost per task | N/A |
Benchmark Deep Dive
The latest Artificial Analysis Intelligence Index (v4.3.2) highlights a tight race at the very top of the frontier model hierarchy, with Anthropic's Claude Opus 5.5 securing the highest aggregate score of 58. This score is derived from a composite of challenging evaluations including GPQA Diamond, MMLU-Pro, and Aider Polyglot. The data reveals that while Opus 5.5 leads in raw intelligence, the gap between it and competitors like GPT-6 Astra and Claude Sonnet 5.5 is narrowing, particularly when cost-performance ratios are considered.
A critical finding in recent evaluations is the diminishing returns of "low-cost" reasoning probes. According to research titled "You Don't Need to Run Every Eval," once the highest-signal benchmarks (GPQA Diamond, MMLU-Pro, MATH-500) are exhausted, remaining low-cost candidates are largely near-duplicates. This suggests that practitioners should focus on these high-signal metrics rather than running exhaustive suites that add little discriminatory value for frontier models.
Furthermore, the emergence of specialized "decision models" presents a challenge to traditional LLM benchmarks. As noted in recent industry coverage, these models are being optimized for specific operational decisions rather than general knowledge retrieval or creative generation. This shift implies that future leaderboards may need to bifurcate further between "General Intelligence" (LLMs) and "Specialized Decision-Making" (Decision AI), as raw MMLU scores become less relevant for enterprise workflow optimization.
Analysis & Trends
- State of the art: Anthropic's Claude Opus 5.5 currently holds the crown for highest intelligence (Score: 58), followed closely by GPT-6 Astra. For pure speed, Celeris-1 dominates with over 1,500 tokens per second.
- Open vs. Closed gap: Open-source models like Llama 4 Scout are competitive in context window size, but closed-source models maintain a lead in aggregate intelligence scores.
- Cost-performance: Granite 4.2 3B offers the most affordable entry point at $0.02 per 1M tokens, while K2 Horizon 375B A23B offers the lowest cost per task among larger models.
- Emerging patterns: The release of Muse Wonder/Full highlights a trend toward "gated" capabilities where premium features (like Muse Code integration) are locked behind higher subscription tiers rather than just API usage fees.
What to Watch Next
- GPT-6.1 Status: Recent reports indicated the cancellation of GPT-6.1 Astra after safety tests; monitoring OpenAI's next frontier launch will be critical.
- Gemini 4 Argon Access: Currently restricted to "Fairwind defenders," broader access could significantly shift the leaderboard if the model performs as predicted.
- Decision AI Benchmarks: Watch for standardized evaluation frameworks emerging for the new wave of "decision models" distinct from LLMs.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
