
AI Coding Assistants — 2026-09-27
Microsoft's sweeping Copilot overhaul — merging chat, coding and "Autopilot" agents into one app — is the biggest development of the past 48 hours, as the company openly positions itself to chase Anthropic and OpenAI in consumer-facing AI coding. Meanwhile, community developers are deep in benchmark-comparability debates, questioning whether leaderboard scores from different evaluation surfaces can be trusted at all. The dominant conversation: with model quality plateauing, harness quality and benchmark transparency are becoming the real differentiators.
AI Coding Assistants — 2026-09-27
Today's Lead Story
Microsoft Overhauls Copilot App With New Coding and Autopilot Agent Features
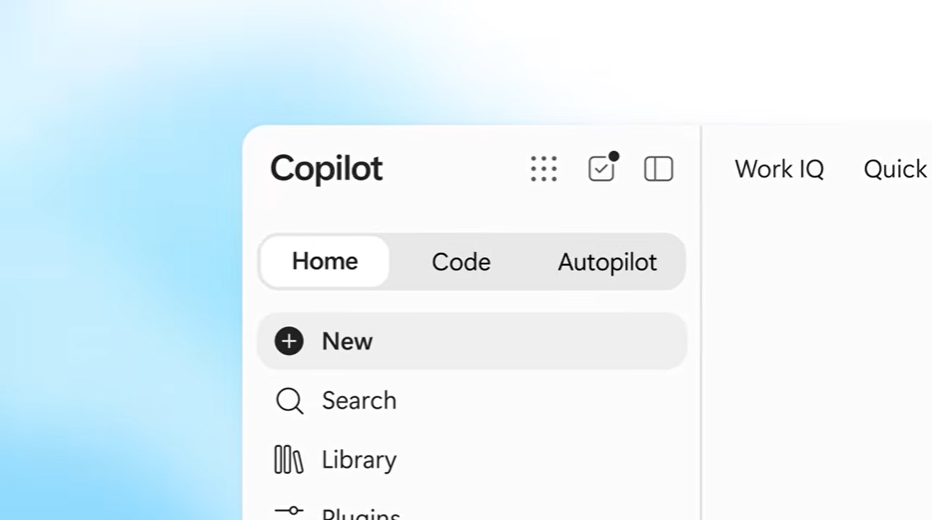
- What happened: Microsoft rolled out a redesigned Copilot app this week that combines chat, coding and AI agents into a single surface, renaming its Scout assistant as "Autopilot." Coverage describes the move as an explicit attempt to rival OpenAI and chase Anthropic amid Microsoft's still-searching AI strategy.
- Who it affects: Developers and casual users in the Copilot ecosystem, plus enterprise teams evaluating Copilot against standalone coding tools like Claude Code and Cursor.
- Why it matters: A unified consumer Copilot app signals Microsoft is no longer treating coding assistance as a purely developer-IDE feature — it's consolidating chat/coding/agents to defend its distribution advantage against Anthropic and OpenAI, which could reshape where everyday coding help flows.
Release & Changelog Radar
- Microsoft Copilot (redesigned app): New coding and document-editing features merged into the consumer Copilot app, with the Scout assistant renamed Autopilot — users get agentic coding and chat in one interface rather than separate tools.
- Heretek-AI Harness Benchmark (report #41): An automated AI Coding Agent Arena evaluation matrix was published on 2026-09-25, generating a fresh leaderboard run — useful raw material for teams comparing agent harnesses side by side.
- AI-Coding-Landscape (community repo): The curated landscape index now tracks GLM-5.3-Flash (Z.ai, released August 26) and the revealed "OX Alpha" stealth model that topped coding leaderboards anonymously before being open-sourced — a good scan of the current model/agent/IDE ecosystem.
Benchmark & Performance Watch
- WebDev Arena: Claude leads coding comparisons with a reported 1,762 Elo in cross-referenced September 2026 benchmark roundups comparing Copilot, Cursor and Claude Code.
- Benchmark comparability (ai-bench issue #233): Community review found the same model scoring 49 vs 54.6 (and 12.6 vs 21.2) on terminal_bench_4_0 depending on which evaluation surface was used, with multiple rows "restamped daily" — a caution that leaderboard deltas may reflect harness differences, not model progress.
Developer Sentiment Pulse
- GitHub (ai-bench issue tracker): Benchmark developers flagged that identical models produce wildly different scores across Artificial Analysis surfaces — "8 rows restamped daily" — revealing growing frustration with opaque leaderboard methodology.
- GitHub (Harness Benchmark): The activity around automated arena reports shows practitioners increasingly favoring reproducible, automated head-to-head agent evaluation over vendor-supplied numbers.
- Tech media framing (CNBC): Analysts read Microsoft's move as a sign the company is "still searching for a winning AI strategy" — community implication being that Copilot's consumer push may came at the expense of developer-tool focus.
Deep Dive: The Stealth-Model Benchmark Problem
One of the most intriguing recent entries in the AI coding landscape is "OX Alpha" — a model that topped coding leaderboards while its identity was hidden, and was only later revealed and open-sourced as part of the GLM family (per the community-maintained AI-Coding-Landscape index, paired with GLM-5.3-Flash, a multimodal MoE with a 1M-token context window, MIT-licensed, at roughly one-tenth Claude-tier pricing with internal benchmarks landing within half a point of Claude Opus 4.8). This matters for two reasons. First, it shows anonymous benchmark entry is now a viable marketing strategy — you can prove capability before revealing provenance. Second, it pressures the benchmark-comparability debate currently playing out in the ai-bench tracker: if the same model scores 49 or 54.6 depending on the surface, "topping a leaderboard" is contingent on the harness, not just the model. For assistants like Cursor, Claude Code and Cline — where the harness wraps the model — this means harness quality may now be a bigger differentiator than model choice, and buyers should weight harness-level head-to-heads (like the Harness Benchmark arena run) over raw model leaderboards.
Business & Funding Moves
- Microsoft: Launched the overhauled Copilot app combining chat, coding and Autopilot agents, explicitly framed as a bid to rival OpenAI and chase Anthropic — a consolidation play on its distribution advantage.
- Cognition (watch item): Latest known: raised $2B at a $48B valuation earlier this month for coding agent Devin, with investors signaling AI coding is "far from a winner-take-all market" — context for how Microsoft's consolidation will be measured against the fragmented agent market.
What to Watch Next
- How quickly Microsoft's Autopilot agents gain traction versus OpenAI's consumer coding surfaces — watch follow-up usage reporting over the coming week.
- The next automated Harness Benchmark arena run — sequential reports (like #41) build trend lines worth comparing over time.
- Whether the ai-bench maintainers resolve the equal-rank/daily-restamping comparability issue, which could change how all coding leaderboards are read.
Reader Action Items
- Try the newly overhauled Copilot app's coding + Autopilot agent flow and compare it to your current assistant on a real task before picking a primary tool.
- Pull the 2026-09-25 Harness Benchmark arena report and cross-check any model you're evaluating against at least two benchmark surfaces before trusting a single headline score.
- Review the AI-Coding-Landscape repo for cheap frontier-grade alternatives — entry-level models like GLM-5.3-Flash at $0.075/$0.25 per million tokens may undercut your current assistant's cost for routine coding work.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
