
Evals and Leaderboards: LMArena, SWE-bench, ARC-AGI — 2026-10-18
Moritz Hardt's latest critique in *Quanta Magazine* argues that current AI benchmarks are "fundamentally broken" and calls for a return to scientific rigor in evaluation. Meanwhile, Meta's release of Muse Spark Open has intensified the "China vs. US" narrative in leaderboard rankings, with independent hubs like Epoch AI providing critical cost and capability data to counter vendor claims.
Evals and Leaderboards: LMArena, SWE-bench, ARC-AGI — 2026-10-18
Top developments
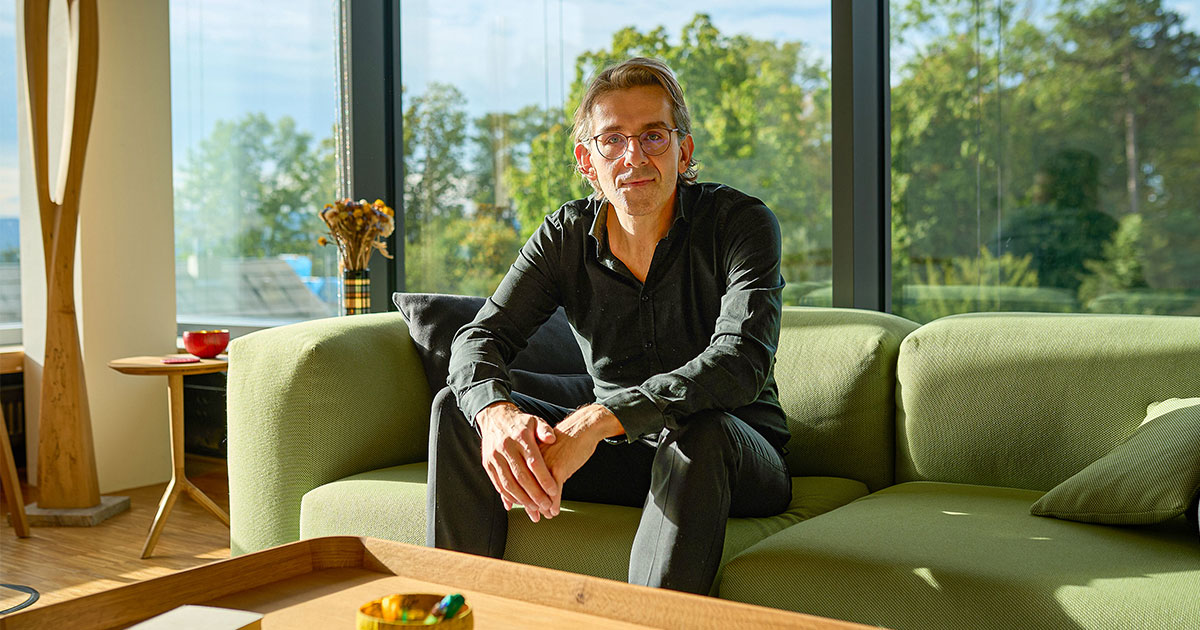
Quanta Profile: Moritz Hardt on the "Dark Art" of Benchmarking
In a feature published on October 16, 2026, Quanta Magazine profiles Moritz Hardt, author of a new book on AI evaluation. Hardt argues that standardized tests for AI are "fundamentally broken" due to a lack of scientific rigor and susceptibility to gaming, though he maintains they are "not unfixable." This piece provides a high-profile theoretical backdrop to recent practical disputes over leaderboard integrity.
Meta’s Muse Spark Open Enters the Fray
On October 15, 2026, Meta released Muse Spark Open, an open-weight AI model positioned as a direct competitor to top Chinese developers. Reports indicate the model is optimized for Apple M5 Ultra chips, marking a rare hardware-software alignment. This release is expected to shake up the "open model" leaderboards, particularly in regions where Chinese models currently dominate open-weight rankings.
Epoch AI Updates Capabilities Hub
Epoch AI updated its Capabilities and Benchmarking Hub on October 17, 2026, offering fresh CSV and ZIP downloads for model performance and cost trajectories. The hub serves as a vendor-free reference point, providing free data under a Creative Commons license. This update is crucial for enterprises seeking to avoid "cherry-picked" vendor numbers, offering a reproducible baseline for cost-per-task analysis.
Brookings Briefing on National Evaluation Strategies
A background briefing distributed for the FCAI dialogue (September 15, 2026) was highlighted in a Brookings report on October 16, 2026. The guide explores how different countries are evaluating AI models, noting the divergence in methodologies. This context is vital as global stakeholders debate whether national leaderboards should prioritize safety, capability, or economic impact.
Local view
Chinese Tech Media & Stakeholders Local Chinese platforms are closely monitoring the entry of Meta's Muse Spark Open, framing it as a strategic move by US tech giants to counter Chinese open-weight dominance. Bannedbook (via RFI) highlights the "rare alliance" of Meta and Apple, suggesting that hardware optimization is becoming a key differentiator in model utility. Meanwhile, Zhihu discussions (updated Oct 13-16) note that the recent influx of models from both US and Chinese labs has led to a "highly aligned" intelligence level, where the gap between the top 10 models on aggregators like Artificial Analysis is narrowing to just 6 points, making leaderboards increasingly noisy and difficult to interpret.
Context & numbers
- SWE-bench Verified Leaderboard: As of recent updates, Claude Fable 5 leads the 117-model leaderboard with a score of 0.950. This benchmark, consisting of 500 verified software engineering problems from real GitHub issues, remains a primary metric for coding capability.
- Terminal-Bench 4.0: The public board remains led by Opus 5.5 with a score of 64.8%. Recent October updates added results for Muse Wonder Full/Wonder, Step 5 Preview, and Mistral Large 4, though cross-harness rankings remain complex.
- Cost Trajectories: Epoch AI’s "The Plunging Price of Thought" analysis highlights that LLM costs have fallen by a factor of 1000 since the release of GPT-3, with recent analyses showing drops of 9–900× per year across various benchmarks.
On the radar
- Contamination-Resistant Benchmarks: A recent arXiv paper (May 2026, but gaining traction in current discussions) proposes methods to make benchmark datasets "contamination-resistant" to prevent inversion attacks that recover input information from KV cache representations.
- Leaderboard Aggregation Noise: With the rapid release of models like Muse Spark Open and Gemini 3.6 Flash, aggregators like LMSys Chatbot Arena and Artificial Analysis are seeing increased volatility. Users are advised to cross-reference with independent hubs like Epoch AI rather than relying on single-source vendor claims.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
