
Inference Efficiency: MLPerf, Tokens per Dollar, Hardware — 2026-09-16
MLCommons released MLPerf Inference v6.1 results on September 16, 2026, marking a participation record and introducing agentic benchmarks. NVIDIA’s Vera Rubin NVL72 debuted with significant efficiency gains over GB300, while DeepSeek’s recent price cuts continue to pressure the cost-per-token landscape.
Inference Efficiency: MLPerf, Tokens per Dollar, Hardware — 2026-09-16
Top developments
MLPerf Inference v6.1 Sets Participation Records with Agentic Benchmarks
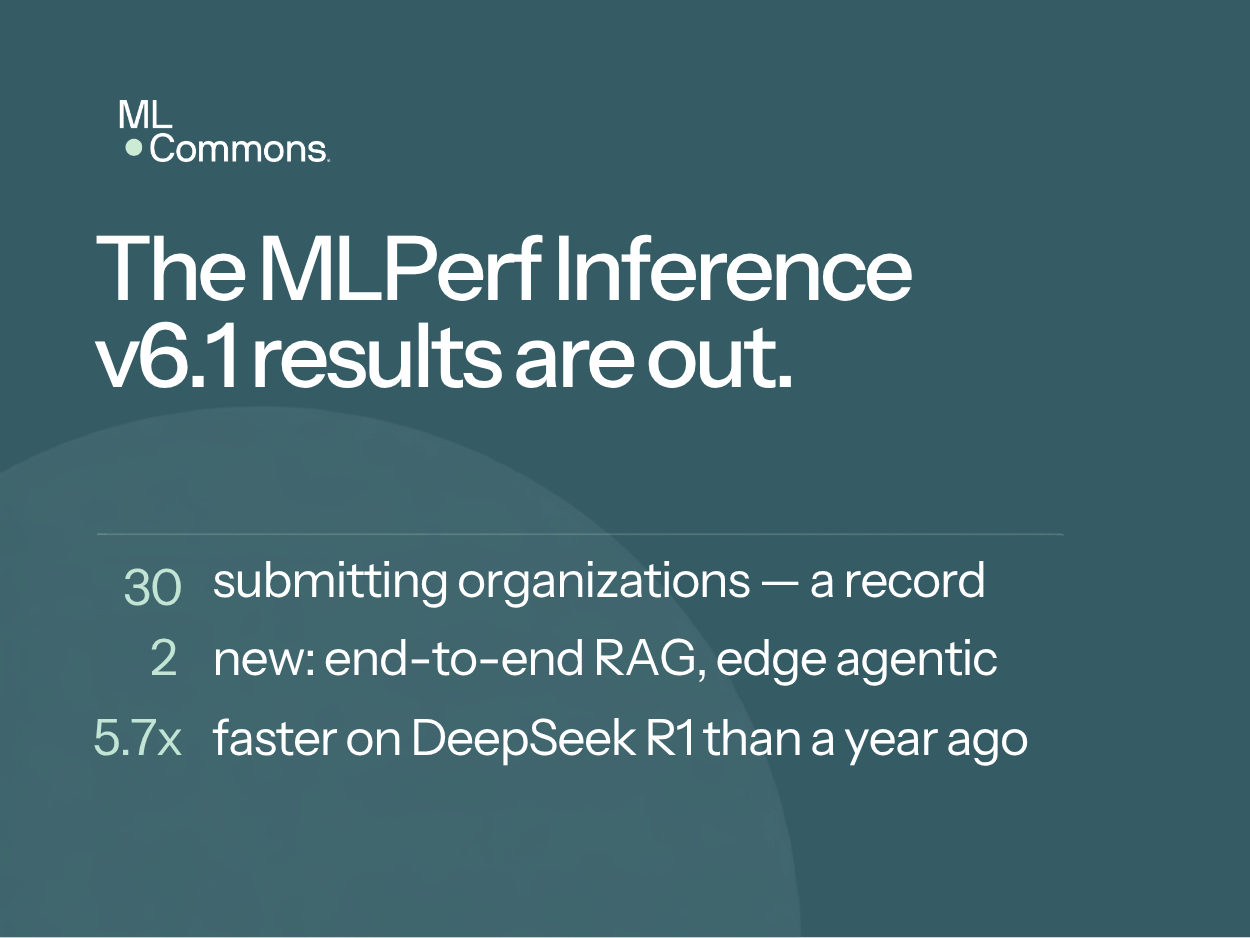
On September 16, 2026, MLCommons announced the results for MLPerf Inference v6.1, noting a new high-water mark for submitting organizations. The release introduces two new tests aligned with emerging AI deployment patterns, specifically Agentic Inference and End-to-End RAG. This expansion aims to measure LLM serving systems under growing context and closed-loop agent workflows, moving beyond static single-turn queries.
NVIDIA Vera Rubin NVL72 Debuts with 3.7x Throughput Gain
NVIDIA submitted its first preview results using the Vera Rubin NVL72 systems in the v6.1 round, claiming up to 3.7x better throughput compared to the previous generation GB300 NVL72. Separate benchmark data from NVIDIA’s AI Infra Summit suggests the Rubin platform delivers up to 30 times more AI agent workload per megawatt than GB300, though these figures are from early silicon and specific coding-agent sessions.
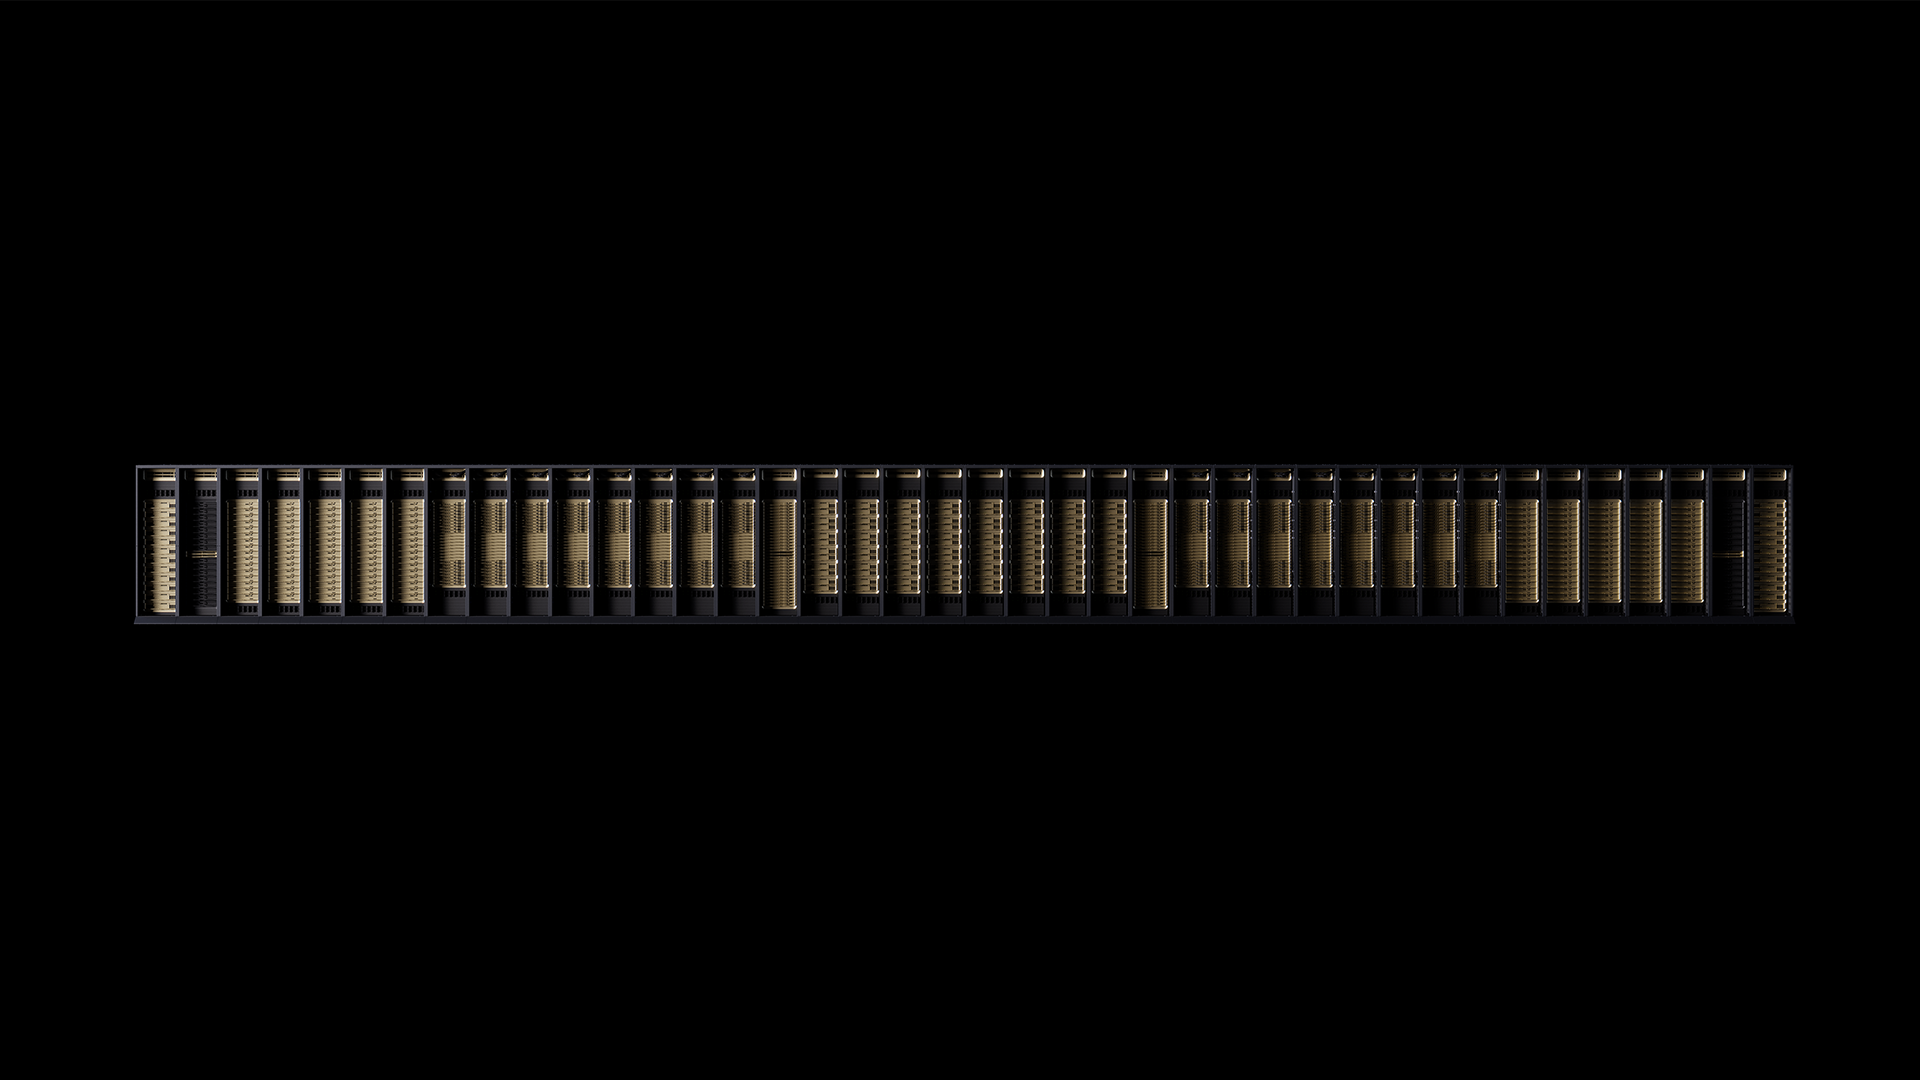
CoreWeave Connects Hundreds of Rubin GPUs in Multi-Rack Cluster
CoreWeave announced on September 16, 2026, the bring-up of multi-rack NVIDIA Vera Rubin NVL72 on its cloud platform, placing hundreds of Rubin GPUs into a single scale-out cluster. This infrastructure move is designed to support agentic AI workloads that require massive parallelism and low-latency interconnects. The deployment follows CoreWeave’s earlier claims of leading inference performance in MLPerf v6.0 using GB200 and GB300 systems.
NVIDIA DSX MaxLPS Boosts Token Throughput Per Megawatt
NVIDIA showcased new energy efficiency optimizations featured on Vera Rubin platforms, claiming a 40% increase in token throughput per megawatt via its DSX MaxLPS technology. Lambda reported that these optimizations helped their cluster jump to 5 million tokens per second. These metrics are critical for data center operators balancing performance demands with power constraints.
Local view
In the Chinese market, cost pressures remain intense following DeepSeek's price cuts announced on September 10, 2026. V2EX users reported that while Alibaba Cloud has deployed DeepSeek-v4.1-flash, prices are approximately 50% higher than official rates during peak times. Meanwhile, Zhihu analyses highlight that GLM-5.3-Flash is now pricing at ~0.13 CNY/M token, slightly undercutting DeepSeek-v4-flash, indicating fierce competition among domestic model providers to lower inference costs per million tokens.
Context & numbers
- MLPerf v6.1: 30 submitters logged in the latest round, with StorageReview noting a 5.7x per-accelerator gain in specific configurations.
- Vera Rubin Efficiency: Early benchmarks suggest up to 30x more AI agent workload per megawatt compared to GB300 NVL72.
- Lambda Throughput: Achieved 5 million tokens per second on NVIDIA Vera Rubin platforms using DSX MaxLPS optimizations.
On the radar
- Independent Verification: TechTimes notes that the 30x efficiency claim for Vera Rubin covers only coding-agent sessions on early silicon; independent third-party verification is pending.
- Agentic Benchmark Adoption: Watch for how quickly the new Agentic Inference test in MLPerf v6.1 is adopted by other hardware vendors like AMD and Groq in subsequent rounds.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
