
Inference Efficiency: MLPerf, Tokens per Dollar, Hardware — 2026-10-15
Recent developments highlight a critical divergence in AI inference economics: while hardware benchmarks like MLPerf v6.1 reveal significant software-driven gains for AMD and NVIDIA, independent analyses suggest that raw token pricing is no longer the sole determinant of cost efficiency. New research into FP4 quantization and speculative decoding promises to lower memory costs and increase throughput, challenging the dominance of traditional GPU-centric metrics.
Inference Efficiency: MLPerf, Tokens per Dollar, Hardware — 2026-10-15
Top developments
DualQuant Eliminates Calibration Data for FP4 Inference
On October 14, 2026, d-Matrix introduced DualQuant, a new LLM quantization method that matches SmoothQuant’s accuracy on Llama and Mixtral models without requiring calibration datasets. This method delivers up to 2.61x memory reduction on real FP4 hardware, significantly lowering the barrier to deploying efficient inference on next-generation accelerators. By removing the dataset dependency, DualQuant accelerates the adoption of FP4 precision, which is critical for maximizing tokens-per-dollar metrics in constrained hardware environments.
Benchmarking Chaos: Seven Tools Yield 20x Variance in Latency
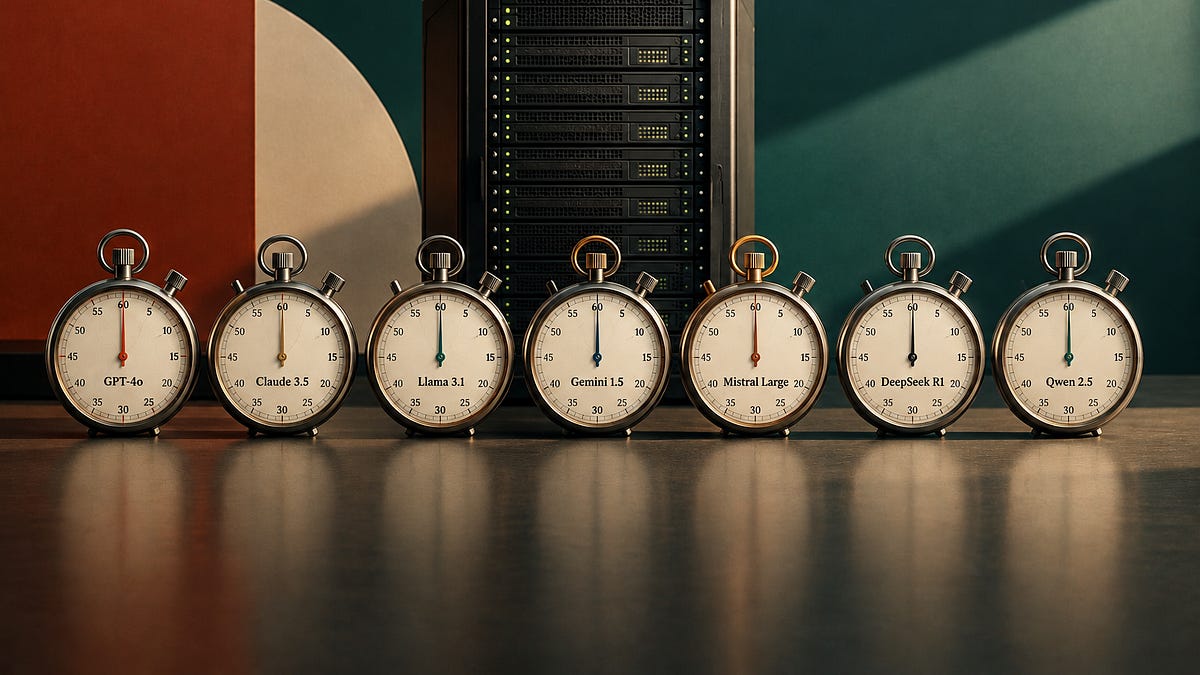
A recent analysis published two days ago revealed that benchmarking the same server with seven different tools results in up to a twenty-fold difference in p99 time-to-first-token. The study highlights that peak throughput rates identified by some concurrency sweeps are often unsustainable under real-world load conditions. This discrepancy underscores the difficulty in validating "tokens per second" claims and suggests that current MLPerf-style static benchmarks may not fully capture dynamic serving realities.
The "Yardstick" Problem: Industry Struggles to Prove Value
An opinion piece from October 14, 2026, argues that the AI infrastructure industry lacks a standardized metric to prove the value of what it sells, leading to opaque pricing and performance claims. The author contends that without a universal "yardstick" for inference efficiency—beyond simple token counts—buyers cannot effectively compare ASICs against GPUs or assess the true cost-per-outcome. This critique aligns with recent disputes over whether software optimizations (like those seen in AMD's ROCm gains) should be weighted equally with hardware leaps in benchmark rankings.
Local view
Chinese Media Focuses on Domestic Compute Economics
Local stakeholders and media outlets are increasingly scrutinizing the cost-efficiency of domestic AI models compared to Silicon Valley counterparts. A report from 21st Century Business Herald (21jingji.com) published on October 14, 2026, discusses how "cost-performance" ratios are shifting as US models drop prices, questioning the remaining advantage of Chinese providers like DeepSeek. The article highlights that while DeepSeek offers low per-token costs, the total cost to complete complex tasks may still be higher due to architectural differences.
Additionally, Huxiu reported on October 14 that OpenAI is pushing for "effective intelligence per dollar," moving pricing models away from simple token counts toward task-value metrics. This shift resonates with local analysts who argue that limiting access via rate limits (429 errors) indicates supply constraints in domestic compute resources, making "tokens per dollar" a misleading metric if availability is inconsistent.
Context & numbers
- MLPerf v6.1 Recalibration: Independent recomputation of MLPerf Inference v6.1 results indicates that headline performance gains of 5.7x drop to 3.04x when filtered for "Available" hardware only. Software optimizations alone moved AMD's performance by 37.9% on fixed MI355X hardware, challenging the notion that hardware upgrades are the primary driver of recent efficiency gains.
- Cost Per Token Dynamics: While not all data points are fresh, recent comparisons show that output and reasoning tokens can constitute ~60% of the bill for agent workloads. Some providers see price doubles for flash-tier models expected in early 2027, indicating volatility in the tokens-per-dollar market.
On the radar
- Speculative Decoding Security: A new arXiv paper (submitted ~1 week ago) analyzes "Secure Speculative Decoding," quantifying the trade-off between acceptance rates and security in lossy systems used by vLLM and TensorRT-LLM. This could impact how enterprise users evaluate the risk-adjusted cost of high-throughput speculative decoding setups.
- Ascend Component Open-Sourcing: DeepSeek's open-sourcing of Ascend platform components (TileLang and compute libraries) continues to be discussed, with potential implications for lowering migration costs to Huawei's Ascend 950 hardware. This move aims to create a CUDA-like ecosystem that could alter the ASIC vs. GPU cost comparison landscape in non-Western markets.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
