
Inference Efficiency: MLPerf, Tokens per Dollar, Hardware — 2026-09-27
This week's big story is MLPerf Training v6.1's first-ever LLM post-training benchmark — a 397B-parameter agentic RL workload run on 256 Blackwell Ultra GPUs. On the cost side, an Anthropic/OpenAI price cut within hours of each other fueled talk of an "inference price war," while DeepSeek's closed-door investor meeting revealed a pivot to Huawei Ascend chips and a $7.5B raise. Cisco also published the industry's first multi-vendor heterogeneous MLPerf Inference submission.
Inference Efficiency: MLPerf, Tokens per Dollar, Hardware — 2026-09-27
Top developments
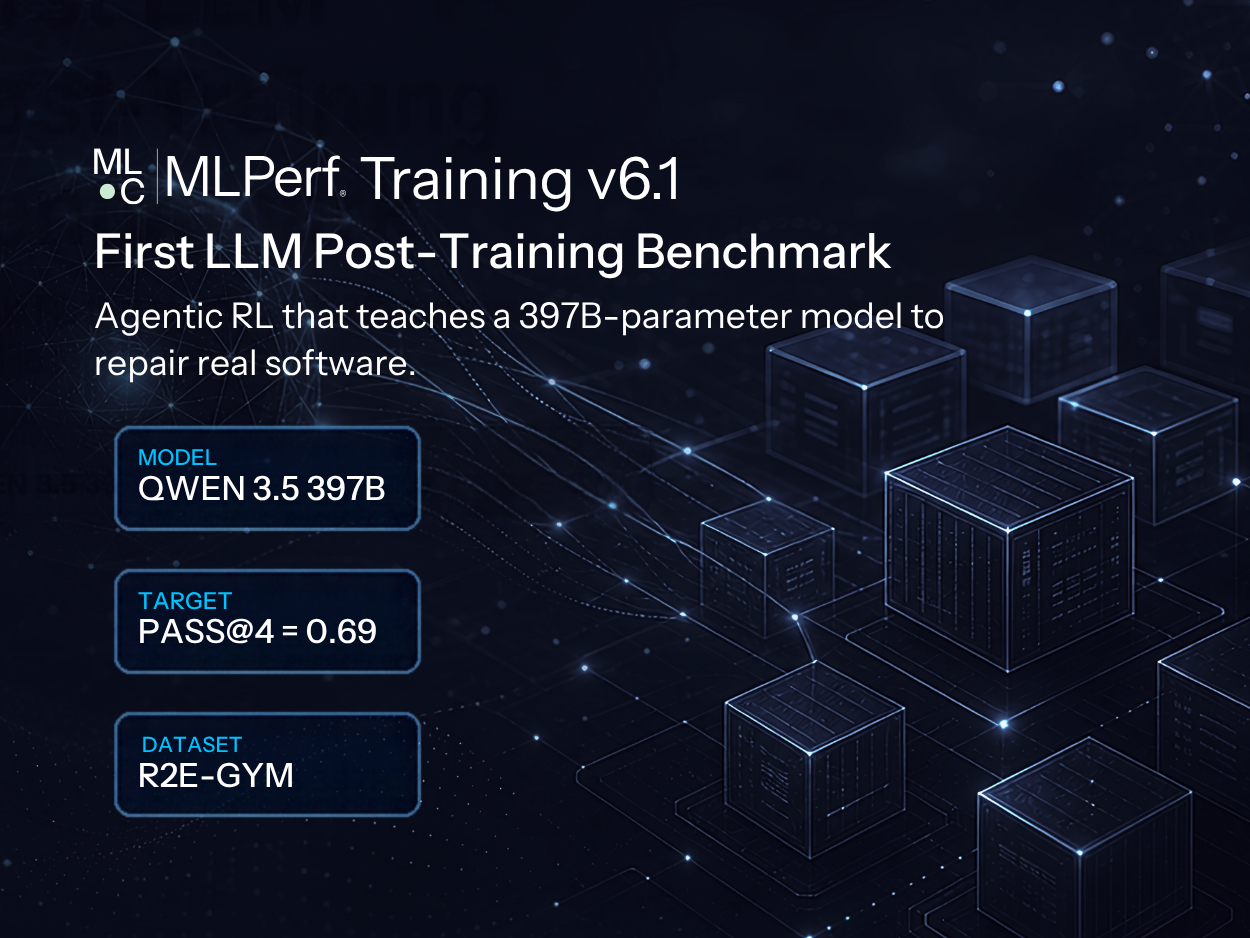
MLPerf Training v6.1: First LLM post-training benchmark
MLCommons added a new agentic RL benchmark to MLPerf Training v6.1 that teaches a 397B-parameter model to repair real software, with a reference run on 256 Blackwell Ultra GPUs. This marks the suite's first formal treatment of the fast-growing post-training/reinforcement-learning workload class, giving buyers a peer-reviewed way to compare training systems on a use case that increasingly dominates real compute spend.
Cisco submits industry's first multi-vendor MLPerf Inference run
Cisco published what it calls the industry's first MLPerf Inference benchmark across mixed-vendor GPU accelerators, arguing operators can orchestrate workloads across heterogeneous GPU pools "without penalties" and improve datacenter unit economics. For the MLPerf community, a heterogeneous hardware submission is a notable precedent — it sidesteps the usual single-vendor framing and speaks directly to the ASIC-versus-GPU cost question.
Anthropic and OpenAI slash inference prices within hours of each other
Both labs cut inference pricing almost simultaneously this week, with rate cards now showing Opus 5.5 at roughly $4/$20 per 1M tokens and GPT-6 Sol at $2/$10 per 1M tokens. A cross-provider survey found the same open model can cost 9x more on one inference provider than another, arguing buyers should rank providers on cost per outcome, not per token.
DeepSeek training pivot to Huawei Ascend, $7.5B raise and 10x revenue jump
Chinese media (September 23) cite The Information reporting that DeepSeek founder Liang Wenfeng told a closed investor meeting the company is shifting large-model training to Huawei Ascend chips and is training a 2-trillion-parameter model. A September 25 Weibo-reported claim says DeepSeek completed a $7.5 billion financing round, with annualized revenue rising from under $500M to about $1B and API prices recently raised 2.3–4.5x. If DeepSeek sustains large-scale training on Chinese silicon, it would be the strongest datapoint yet on domestic alternatives to Nvidia in the tokens-per-dollar race.
Local view
Chinese-language tech media framed the week around token economics: Huxiu covered an Epoch report finding that the cost of inference for fixed AI capability falls roughly 13x per year, describing intelligence as becoming a "priced infrastructure." Zhihu developers compared domestic model pricing tiers, noting Zhipu's GLM-5.3-Flash at about ¥0.13 per million tokens (time-limited 50% off), slightly below DeepSeek v4-flash pay-as-you-go.
Context & numbers
- Opus 5.5: $4 input / $20 output per 1M tokens; GPT-6 Sol: $2 / $10 per 1M tokens
- DeepSeek annualized revenue reportedly rose from <$500M to ~$1B; $7.5B raise (Weibo-reported, unconfirmed by the company)
- On one agent workload, output and reasoning tokens are ~60% of the bill; Opus 5 cost 3.6x Grok 4.6
- GPT-4-equivalent inference fell from ~$20/M tokens (late 2022) to ~$0.40/M tokens; H100 cloud prices stabilized at $2.85–3.50/hr after a 64–75% drawdown
On the radar
- MLPerf Training v6.1 likely spurs vendor submissions on the new post-training benchmark; watch for first vendor results beyond the 256-GPU Blackwell Ultra reference run
- DeepSeek's GTX hour windows vs. flat-price providers: batch-routing can reportedly halve bills on DeepSeek V4 Pro, which doubles rates in two UTC windows
- Gemini 3.8 Flash is scheduled to double in price on January 1, 2027 — flag for annual budget planning
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
