
Speech, Voice and Realtime Audio Models — 2026-10-31
The voice AI sector is experiencing significant momentum with Nvidia releasing a new open-source transcription model supporting 40 languages and AssemblyAI launching a highly competitive text-to-speech API. Meanwhile, NTT has developed a bidirectional voice dialogue AI that reduces response times by over 50%, aiming to enhance call center efficiency. The global market for voice AI agents is projected to reach $43.83 billion by 2036, driven by enterprise automation.
Speech, Voice and Realtime Audio Models — 2026-10-31
Top developments
Nvidia Unveils Open-Source Transcription Model
Nvidia has released a new free speech-to-text model capable of transcribing up to 40 languages, including distinguishing speakers in overlapping conversations. This model achieves the highest accuracy among open-weight models but is limited to recordings rather than live audio, positioning it primarily for meeting and medical transcription tools. The release highlights the growing demand for high-accuracy, multilingual transcription in non-realtime applications.

AssemblyAI Launches Cost-Effective TTS API
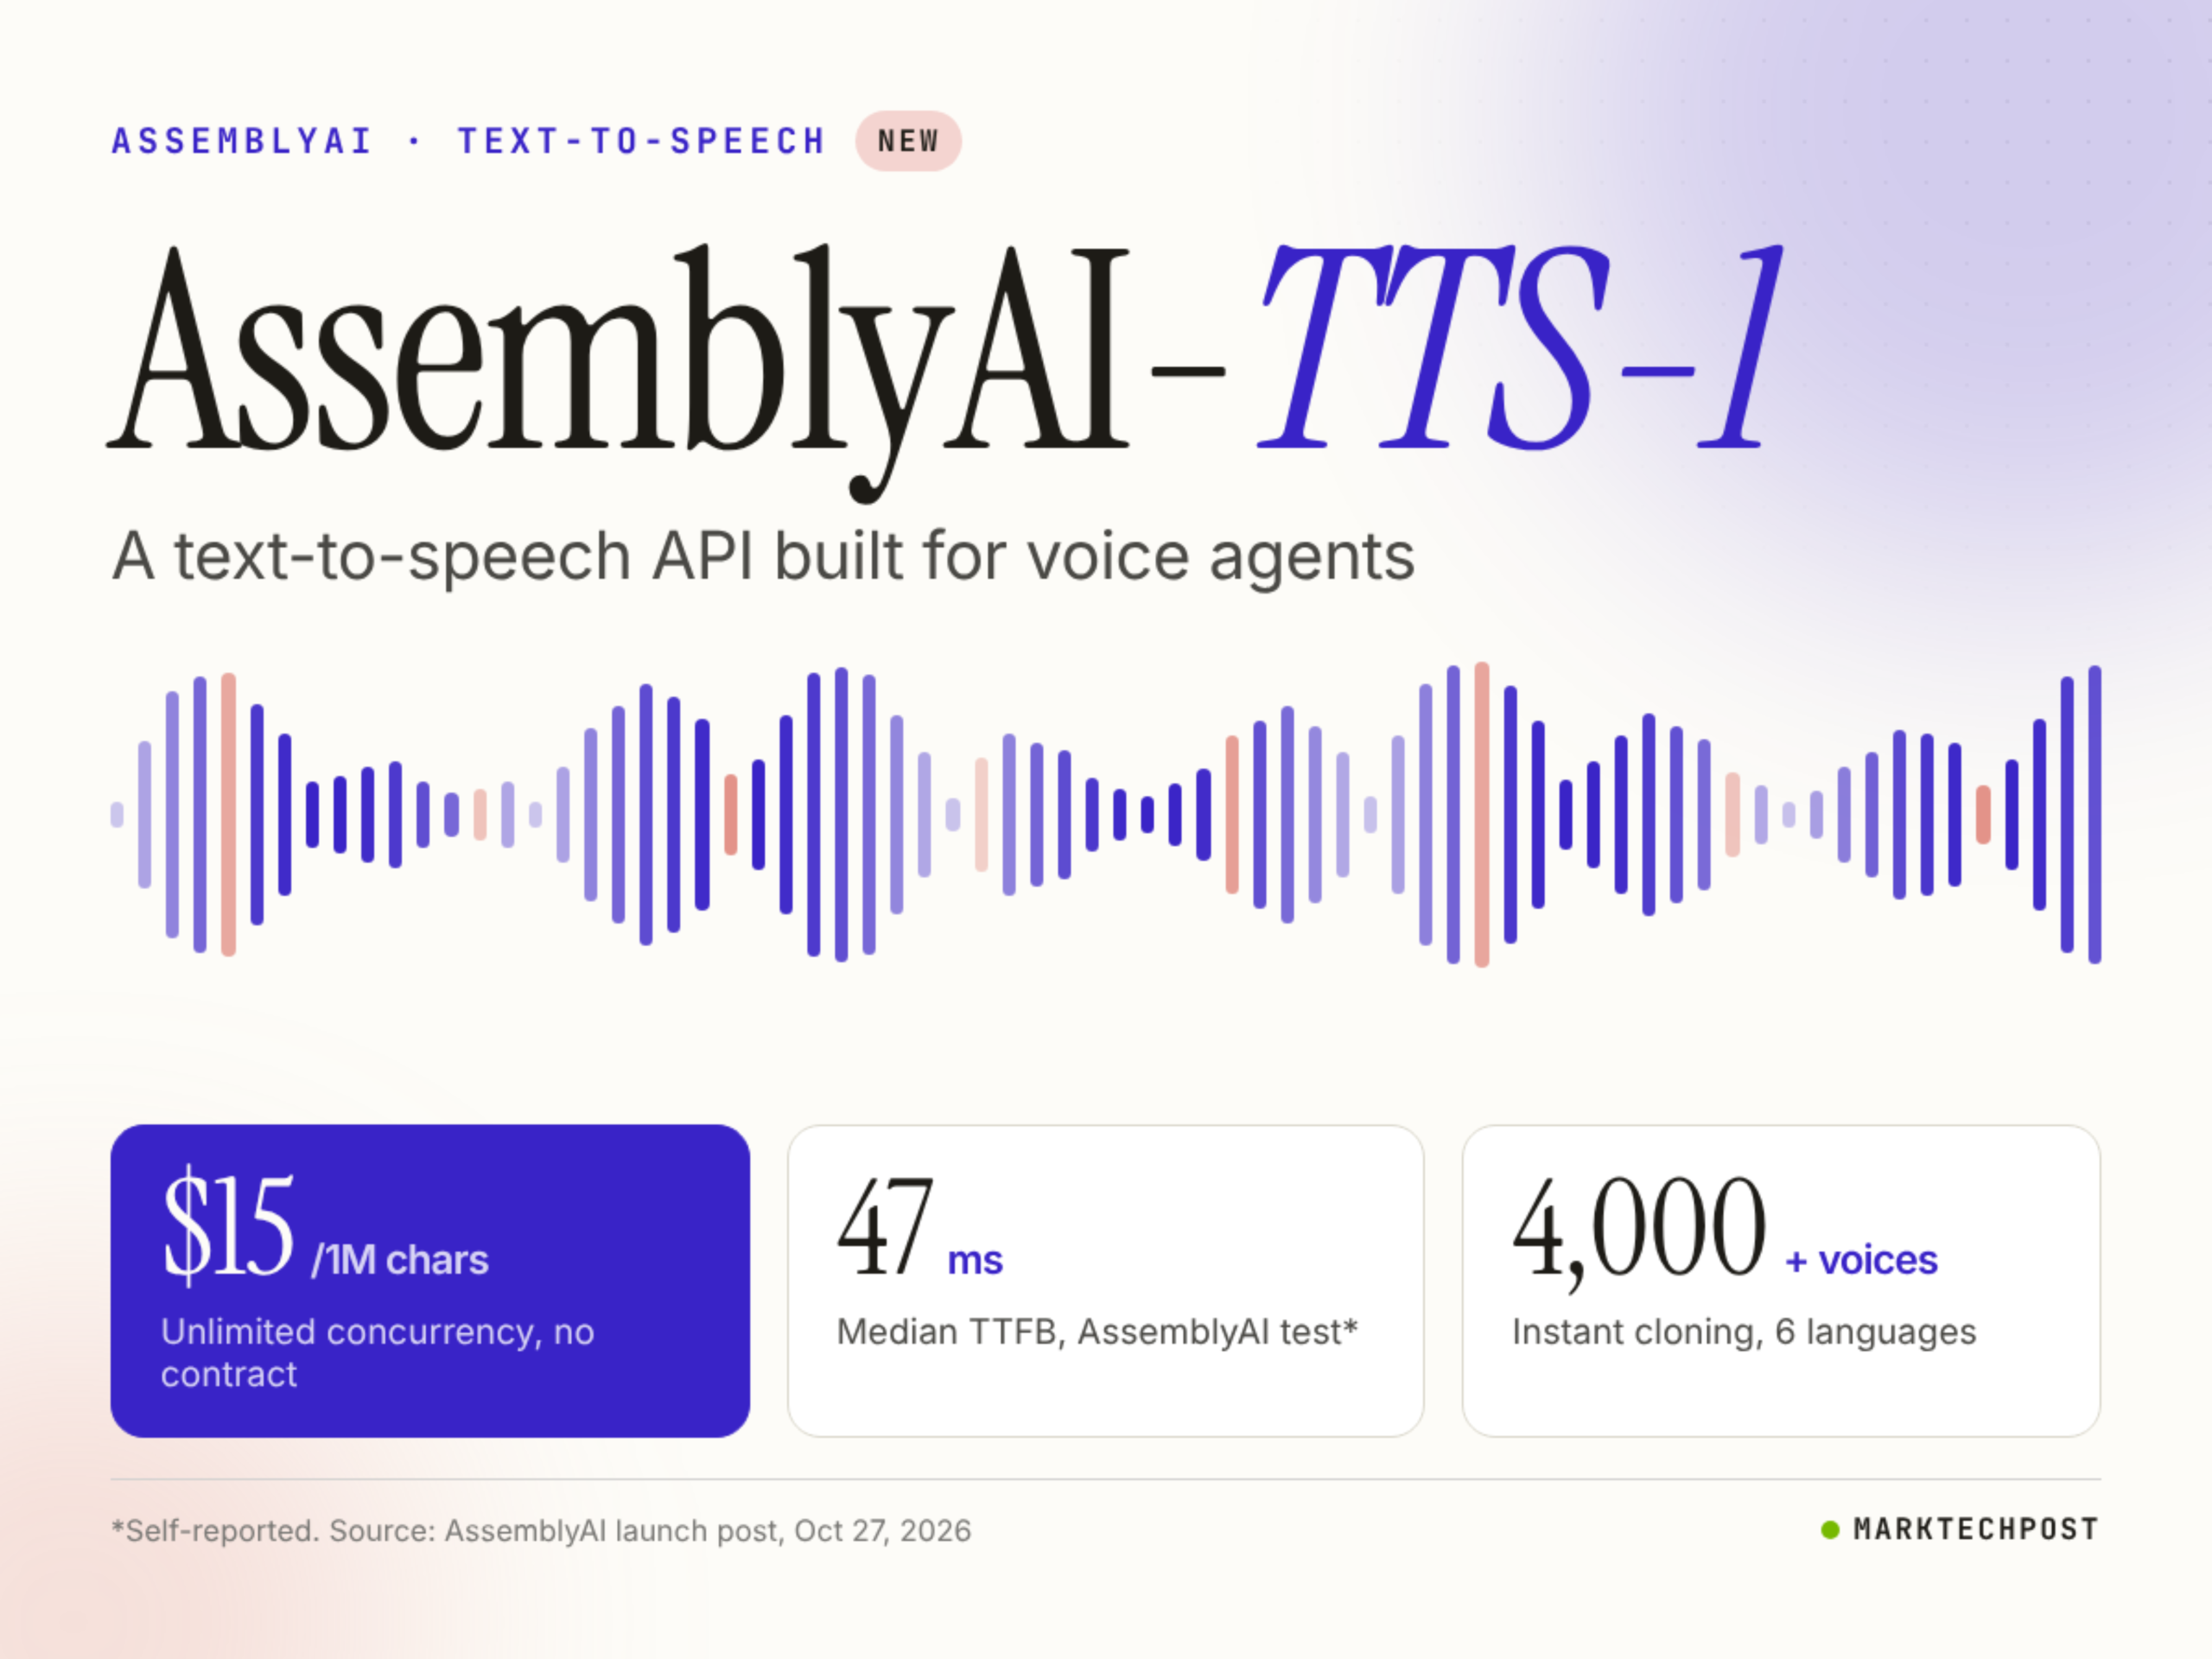
AssemblyAI has shipped AssemblyAI-TTS-1, a streaming text-to-speech API specifically designed for voice agents. Priced at $15 per 1 million characters, the service offers unlimited concurrency, making it a compelling option for developers building scalable voice applications. This pricing strategy places AssemblyAI in direct competition with other major TTS providers like ElevenLabs and Cartesia, who are also vying for dominance in the voice agent infrastructure market.
NTT Develops Bidirectional Voice Dialogue AI
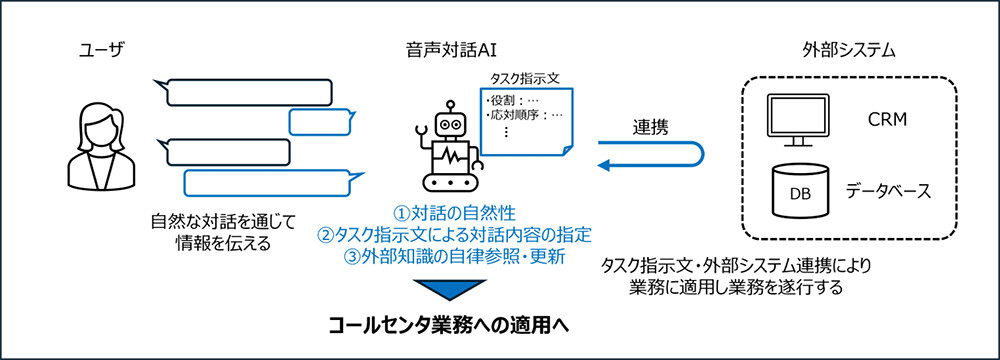
NTT has established a bidirectional voice dialogue AI technology that allows the system to respond while the user is still speaking, mimicking natural human conversation. The technology reduces average response times by more than 50% compared to other services, significantly improving the fluidity of interactions. This advancement aims to enhance call center quality and reduce operator workload by automatically retrieving necessary information and following instructions naturally.
Deepgram Acquires Daily to Strengthen Voice Infrastructure
Voice AI company Deepgram has acquired Daily, the developer of the open-source voice AI infrastructure framework Pipecat. The acquisition aims to bolster Deepgram's capabilities in building voice AI applications, with both parties committing to maintaining Pipecat's open-source nature and vendor neutrality. This move consolidates resources within the voice AI infrastructure space, potentially accelerating the development of robust voice agent frameworks.
Local view
In Japan, ElevenLabs' new "Eleven Realtime" model is generating significant buzz for its ability to break the speed-accuracy barrier in voice AI. The model achieves 98.8% accuracy on Big Bench Audio with sub-600-millisecond response times, offering both "v1 Mini" for natural conversations and "v1 Max" for complex tasks. NTT's recent announcement of its bidirectional voice AI is also being highlighted by local media as a major step toward more natural, human-like customer service interactions.
In South Korea, Nvidia's new open transcription model is being praised for its support of 40 languages and its ability to handle overlapping speech, which is crucial for diverse linguistic environments. Additionally, KT has launched "Token Factory," a platform managing over 500 AI models, including those for speech and language, optimizing token efficiency for Korean prompts.
Context & numbers
The global voice AI agents market is projected to reach $43.83 billion by 2036, growing at a CAGR of 24% as speech-to-speech AI scales in enterprise automation. This growth is driven by the increasing adoption of voice AI for automating high-volume service calls and pairing AI with human support for compliance and quality assurance.
On the radar
- NTT's AI Navigation: NTT TechnoCross will provide an "AI Navigation" feature for its "ForeSight Voice Mining" service starting December 2026, which guides agents in real-time based on conversation content.
- Browser-Based AI Avatars: A Japanese startup has claimed to develop the world's first browser-based voice synthesis and lip-sync AI avatar model that requires no GPU server, potentially lowering the barrier for real-time avatar applications.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
