
오늘의 VLM & VLA 연구 브리핑 — 2026-10-14
Check out the latest VLM and VLA research released since October 12, 2026, featuring a multimodal AI framework for sketch-based BIM generation and a study quantifying the modality gap. Plus, check out ICLR 2026 VLA model analyses and VLM4VLA architecture reviews pointing to new directions in robotic control.
오늘의 VLM & VLA 연구 브리핑 — 2026-10-14
주목할 만한 신규 논문 (최소 3편)
1. A Multimodal AI and Visual-Programming Framework for Sketch-Based BIM: Formalization and Empirical Validation Turning hand-drawn 2D floor plans into object-based BIM models during early architectural design has long been a manual bottleneck. This research proposes a multimodal AI and visual-programming framework to automate sketches into BIM models, aiming to resolve downstream delays in simulation, cost estimation, and coordination.

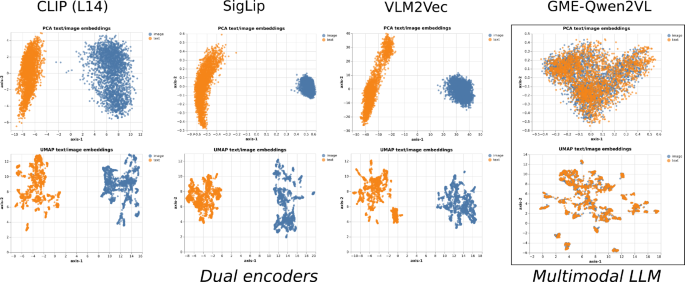
2. Quantifying and reducing the modality gap in both contrastive and generative multimodal vision–language models Dual-encoder VLMs embed text and images into a shared representation space, but a clear separation known as the 'modality gap' exists between embeddings of one modality and another. This study explores methods to quantify and reduce this gap across both contrastive and generative multimodal VLMs.
3. VLM4VLA: Revisiting Vision-Language-Models in Vision-Language-Action Models The VLM4VLA paper takes a fresh look at Vision-Language Models (VLMs) within Vision-Language-Action (VLA) models. It focuses on reassessing the roles and architectural contributions of VLMs when building VLA systems.
VLM 기술 동향 및 상세 요약
멀티모달 LLM의 비전-언어 태스크 가이드 A comprehensive survey and guide published in MDPI covers Multimodal Large Language Models (MLLMs) with a strong focus on vision-language tasks. Topics include image captioning, visual question answering (VQA), cross-modal retrieval, visual grounding, multi-image reasoning, long video understanding, and Embodied AI.

VLM 평가 기준의 변화 The State of the Art Large Vision Language Models survey (v7) outlines a taxonomy of tasks used to evaluate VLMs. In particular, it highlights the shift toward Embodied, Temporal, and Judge-aware evaluations in 2025–2026, while discussing common metric choices and the limitations of current automated evaluation practices.
효율적인 멀티모달 LLM A survey in the Visual Intelligence journal notes the stellar performance of MLLMs in VQA, visual understanding, and reasoning, but points out that massive model sizes and high training and inference costs hinder widespread adoption. Developing efficient MLLMs has emerged as a key challenge.
로보틱스 및 VLA 성과 요약
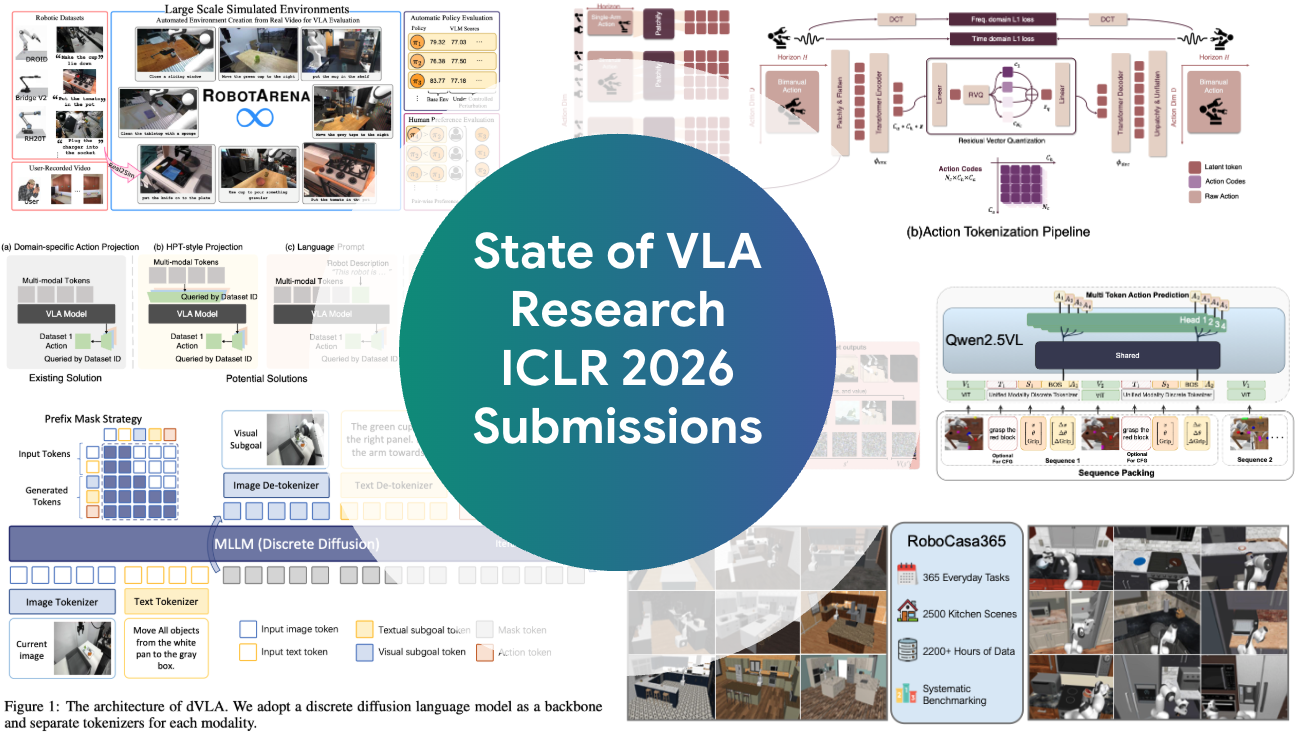
ICLR 2026 VLA 연구 현황 분석 Moritz Reuss's blog post analyzes 164 Vision-Language-Action model submissions to ICLR 2026. This analysis offers insights into discrete diffusion VLMs, reasoning models, and current benchmark trends.
VLA 모델의 개념, 진전, 응용 및 과제 An arXiv paper provides a comprehensive overview of recent advancements in Vision-Language-Action models. This review organizes the conceptual foundations, architectures, and learning paradigms of the VLA field into five thematic pillars, addressing their applications and challenges in robotics.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
