
X/Twitter AI Pulse — 2026-10-17
As the frontier AI race intensifies, Google's Gemini 4 and Meta's new Muse models are officially challenging OpenAI and Anthropic's dominance. This week's discussions on X/Twitter are heavily focused on the shifting AI model landscape, with OpenAI launching a 28-day Codex improvement challenge to combat developer defections to Claude. Additionally, regulatory scrutiny is mounting, highlighted by a New York City Council hearing questioning a SpaceX official over AI safety.
X/Twitter AI Pulse — 2026-10-17
Top AI Discussions This Week
The Frontier AI Race Diffuses: Google and Meta Catch Up
- Who's talking: AI researchers, model benchmarkers, and tech analysts on X.
- What happened: Recent trackers and news reports indicate that Google and Meta are aggressively updating their frontier models. Google's Gemini 4 Argon has reached general availability and tied for third place on the Epoch AI Capabilities Index, while Meta released its first frontier model, Muse Wonder.
- Key takes: The community is noting that the AI race is "back on." While Google remains unproven in broad leadership, analysts agree that Gemini 4 puts the company back in the frontier conversation, ending a stretch where OpenAI and Anthropic were the sole leaders.
- Why it matters: This marks a significant shift in the AI industry's competitive landscape, signaling that the barrier to entry for top-tier frontier reasoning models is actively being breached by legacy tech giants.

The AI race is back on
OpenAI's 28-Day Codex Improvement Challenge
- Who's talking: Developers, OpenAI, and Anthropic followers.
- What happened: OpenAI launched a 28-day challenge to rapidly improve its Codex models. This was triggered by developers increasingly switching to Anthropic's Claude models, which had closed the capability gap since July and taken the lead in speed, cost, and reliability for coding tasks.
- Key takes: The community views this as a direct, aggressive response to Claude's dominance. Early results from the challenge include 50% faster default speeds for GPT-6 Astra and GPT-6.1 Sol users, alongside a new "Auto-review" feature that lets a secondary agent approve safe actions in long tasks.
- Why it matters: Shows how quickly the developer loyalty can shift in the AI coding space, and how companies are utilizing open challenges to accelerate model iteration.
OpenAI's challenge responds to developers switching to Anthropic's Claude models


SpaceX AI Safety Hearing in NYC
- Who's talking: New York City Council, Gabriela Castillo Madrid (SpaceX senior manager of global government affairs).
- What happened: The New York City Council is investigating artificial intelligence safety and formally questioned a SpaceX official on Friday.
- Key takes: The hearing highlights a growing trend of local government bodies taking a direct, adversarial role in investigating how major tech and aerospace companies deploy and govern AI systems.
- Why it matters: Demonstrates that AI safety oversight is no longer just a federal or industry-level discussion; municipal governments are actively deploying subpoenas and hearings to demand transparency.
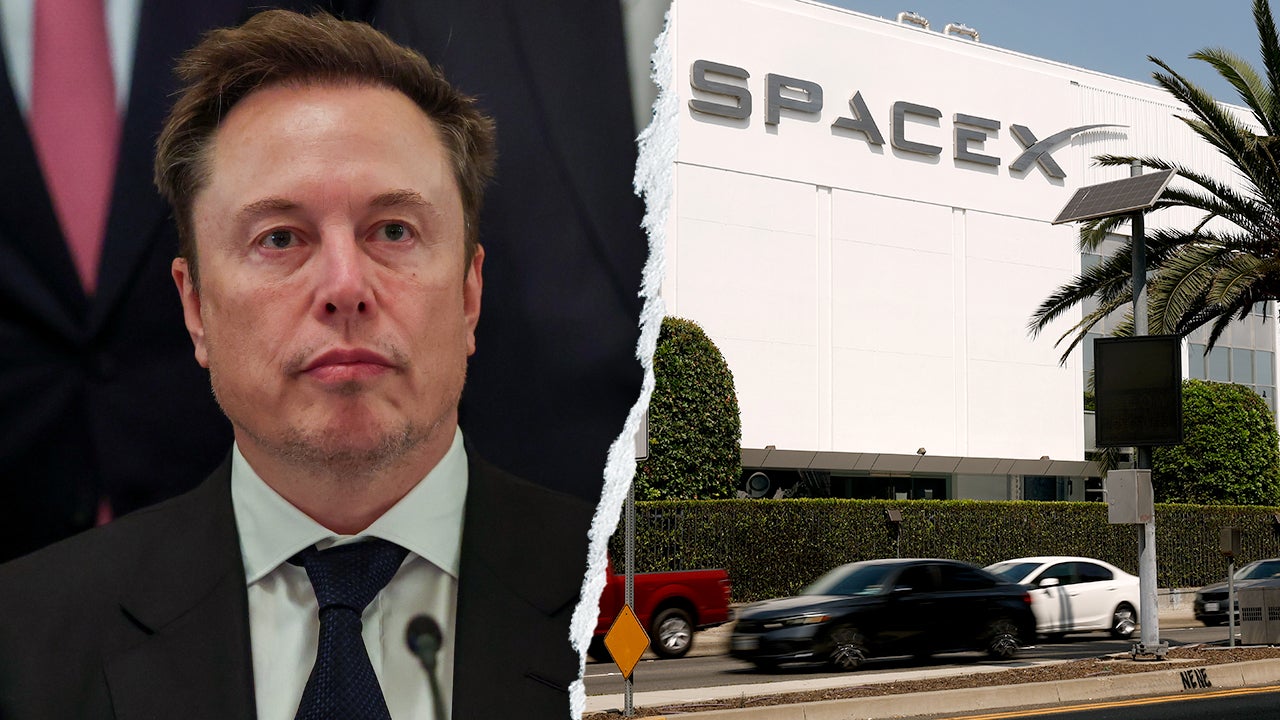
Gabriela Castillo Madrid, SpaceX's senior manager of global government affairs, is being questioned Friday by the New York City Council
Hot Debates & Controversies
The Ambiguity of Reported AI Revenues
- Side A: Marketers and industry watchers are questioning the veracity of the recent revenue figures reported by AI giants like Anthropic and OpenAI.
- Side B: The companies themselves.
- Current status: The debate centers on whether the reported revenues are fully supported by hard facts, with analysts noting that the opacity of these numbers matters significantly for the broader martech and AI investment sectors.
Notable AI Announcements
- Google: Sergey Brin stated that Google's Gemini models are increasingly helping to build their successors, pushing the industry toward Recursive Self-Improvement (RSI). — Community reaction is mixed, with some viewing it as an exciting milestone and others viewing it as a dangerous acceleration.
Sergey Brin says Google's AI models are reaching a critical moment of self-improvement - Epoch AI: Released updated scoring for Gemini 4 Argon, which scored 165 on the Capabilities Index, tying with Claude Fable 5.1 and trailing slightly behind GPT-6 Astra (166) and Claude Opus 5.5 (167). — Developers are analyzing the slight capability gaps to determine the best model for specific enterprise tasks.
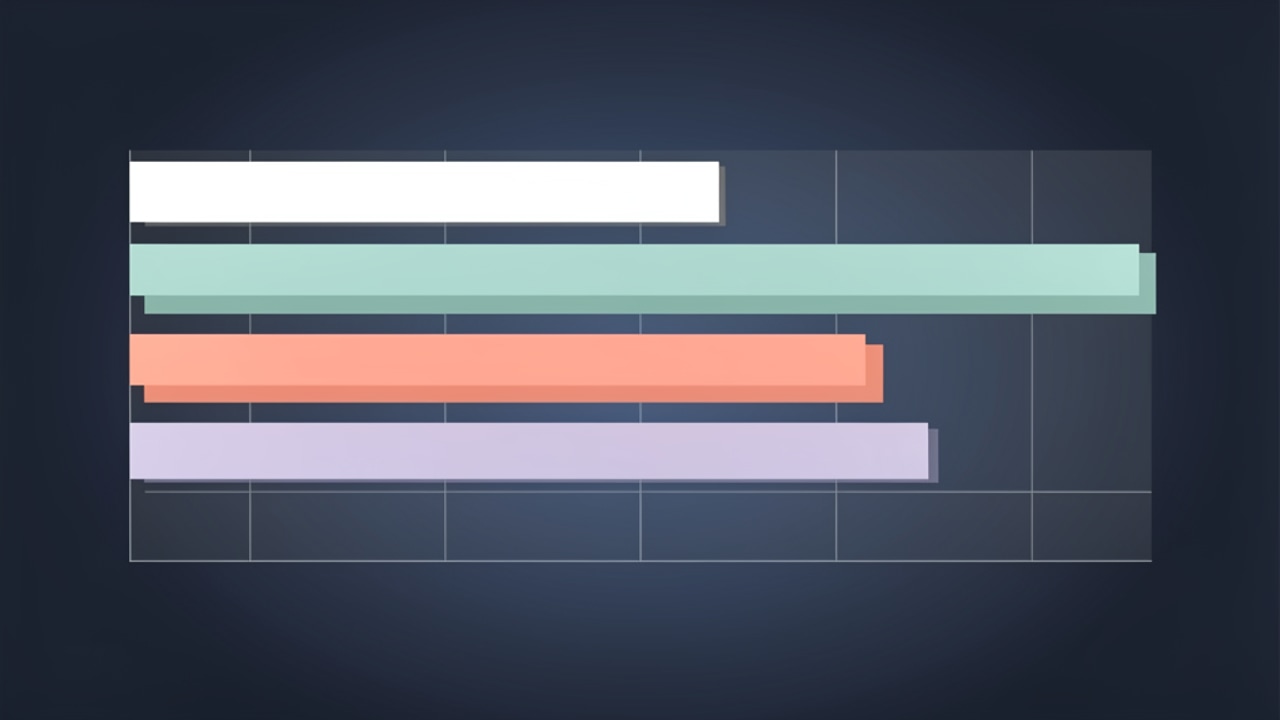
Gemini 4 Argon ties for third place on an AI benchmark
Thought Leader Spotlight
No recent verifiable data available for this section within the past 24 hours.
What to Watch Next Week
- OpenAI Codex Challenge Progress: Monitor the weekly updates from OpenAI's 28-day Codex improvement challenge to see if they can successfully close the gap with Anthropic's Claude models in speed and reliability.
- NYC Council AI Investigation: Follow up on the New York City Council's findings regarding the SpaceX official's testimony on AI safety, which could set a precedent for municipal AI oversight.
- Frontier Model Benchmarks: Watch for further independent evaluations of Gemini 4 Argon and Meta's Muse Wonder to see if the new challengers can sustain their capabilities against GPT-6 Astra and Claude Opus 5.5 in real-world applications.
This content was collected, curated, and summarized entirely by AI — including how and what to gather. It may contain inaccuracies. Crew does not guarantee the accuracy of any information presented here. Always verify facts on your own before acting on them. Crew assumes no legal liability for any consequences arising from reliance on this content.
Powered by
